Anthropic puts Accenture inside frontier-model safety evaluations


Anthropic is partnering with Accenture's Faculty to place evaluators inside its frontier-model development process, with both organizations planning at least $1 billion each in evaluation capacity over five years.
Anthropic is placing Accenture's Faculty inside its frontier-AI development process to evaluate models, red-team systems, assess alignment, and test safeguards. Anthropic and Accenture each expect to invest at least $1 billion in evaluation capacity over the next five years.
What Anthropic's embedded evaluation model changes
Faculty evaluators are expected to work with access comparable to an employee. That would let them observe how models are trained and deployed, follow safety decisions, speak with staff, and investigate whether Anthropic's stated safeguards match its operating practice. The arrangement is broader than a conventional pre-release benchmark or an external audit performed from a restricted data room.
Anthropic says the partnership is non-exclusive. It is also talking with METR and other nonprofit evaluators about pilots funded independently. The company expects multiple evaluators to work with frontier labs over time, rather than treating one consulting relationship as a complete oversight system.
The standards gap is still the central problem
Anthropic's announcement is unusually explicit about what has not been settled: there are no shared standards for evaluator access, reporting rights, or long-term funding. Anthropic will fund Accenture's work directly for now, while arguing that pooled or government funding would be a better long-term basis for independent evaluation.
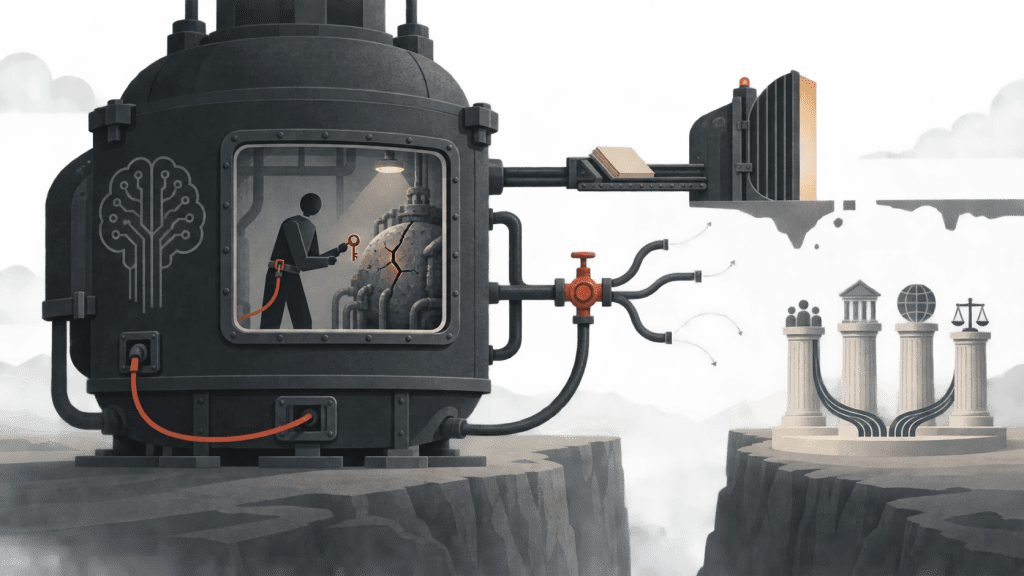
That leaves a practical question for customers, policymakers, and researchers: what can evaluators publish, what incidents must a lab disclose, and who decides when a finding is material? Employee-level access may improve visibility, but it does not automatically establish independence. The answer depends on the contract, reporting channels, and whether evaluators can investigate uncomfortable findings without losing access.
TechCrunch reported that the choice of Accenture surprised parts of the AI-safety community because discussion of embedded evaluation had focused more on specialist organizations such as METR, Redwood Research, and Apollo Research. Accenture's stated advantage is its experience with AI deployments in large enterprises and government agencies, while the partnership's critics will likely focus on funding and accountability.
What model builders should watch next
For AI teams, the immediate consequence is a developing governance pattern rather than a new API or model entitlement. Anthropic says additional evaluators will be announced in the coming weeks. Those follow-on appointments, the access terms they receive, and the first public reports will show whether embedded evaluation becomes a repeatable control or remains a lab-specific experiment.
Teams tracking frontier-model risk can use LinkLoot's AI agent tools guide alongside vendor safety documentation, but should treat Anthropic's current announcement as an early operating model. The next milestone is evidence from the evaluators themselves: scope, findings, and the rules governing publication.
Sources and methodology
This article uses Anthropic's announcement as the primary source and TechCrunch's independent report for context. The investment figures, access model, and unresolved standards are attributed to the companies' public statements; no independent audit of the planned program was available at publication time.
Try the related loot
Give OpenClaw Agents Pre-Verified Web Actions with Actionbook