Cloudflare separates Search, AI Training, and Agent access


Cloudflare's new controls let site owners keep search visibility while disallowing AI training, with new ad-supported domains defaulting to block training and agent traffic.
Cloudflare has replaced its single “Block AI Bots” switch with separate controls for Search, AI Training, and AI Agents. The change gives publishers a way to keep conventional search access while refusing model-training crawlers, and it changes the default posture for newly onboarded domains with advertising.
The rollout went live on September 15, 2026. It matters to publishers, stores, SaaS companies, and anyone who relies on both organic discovery and control over how site content is reused.
What Cloudflare changed on September 15
Cloudflare’s new Training control includes Disallow AI Training, which publishes a no-training preference through robots.txt while keeping qualifying mixed-use crawlers available for search. The company says Google, Apple, and Microsoft have either implemented or committed to honoring the relevant opt-outs.
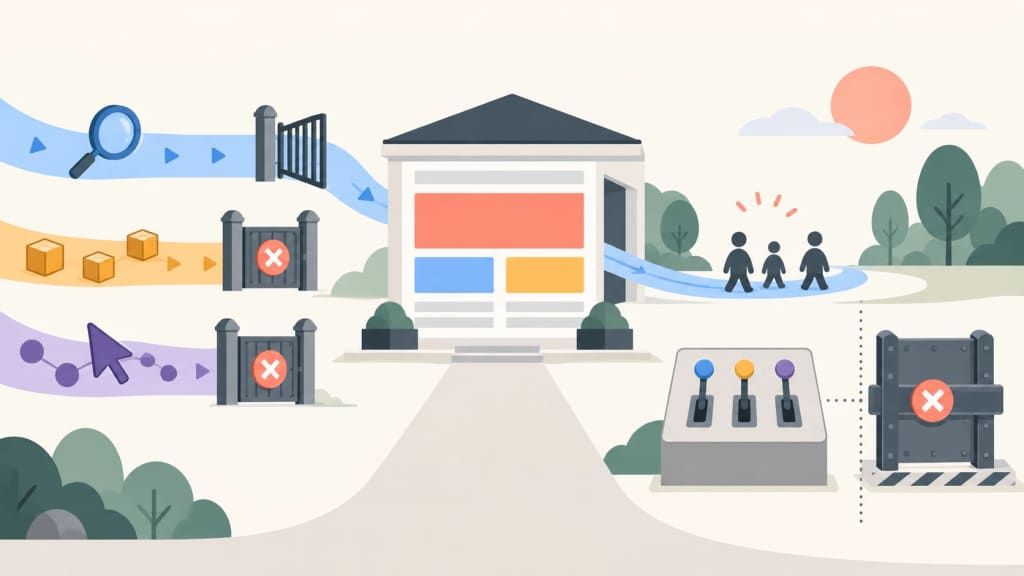
The separate controls distinguish three kinds of automated access:
- Search: crawlers that index content to answer questions later.
- Agent: live, on-demand activity acting for a user, including browser-use assistants.
- Training: crawlers collecting content for model training or fine-tuning.
Cloudflare also introduced an Accountable designation for crawler operators that provide a training opt-out, support controls for AI summaries, expose useful visibility into URL-level use, and keep traditional search results separate from training choices.
The default for new ad-supported domains
For new domains onboarding to Cloudflare, pages that display ads default to allowing Search while blocking Training and Agent traffic. Site owners can change those settings in the dashboard. The default is narrower than a blanket ban: it targets pages where automated access can replace a monetizable human visit, while preserving search discovery as the default path.
Existing settings are migrated. Cloudflare says selections that previously blocked AI training move to Disallow AI Training, while older settings are translated into the new Search, Training, and Agent controls. Owners that need to stop mixed-use crawlers entirely must choose Block, which can also remove those crawlers from search access.
What the setting does for Google, Apple, and Bing
Search Engine Journal reports that Googlebot, Applebot, and Bingbot remain eligible to crawl for search under Disallow AI Training, while the stronger Block option stops them entirely. The implementation differs by provider: Google uses the Google-Extended robots token, Apple uses Applebot-Extended, and Microsoft’s robots.txt support for the same no-training preference is still pending.
That distinction is operationally important. A publisher can reject training use without intentionally removing pages from Google Search, but the choice does not decide whether pages appear in Google AI Overviews or AI Mode. Google controls those experiences through separate Search settings. Bing’s current training signal remains tied to its NOARCHIVE mechanism.
What publishers should review now
- Check whether the domain has advertising or subscription pages that should block live agents by default.
- Decide whether
Disallow AI Trainingmatches the site’s licensing and syndication policy. - Verify Google Search Console settings separately; robots-level training controls do not govern AI Overviews eligibility.
- Test important pages with normal search crawlers and documented AI access paths after changing the policy.
Cloudflare says its next step is a control for how much content appears in AI-generated summaries, targeted for early 2027. For now, the practical decision is whether search visibility, agent access, and training use should share one rule. They no longer have to.
Sources and methodology
This report uses Cloudflare’s September 15 announcement as the primary source and Search Engine Journal’s independent implementation analysis for crawler behavior and provider-specific caveats. Cloudflare’s settings and crawler classifications can change; confirm the current dashboard behavior before changing production access rules.
Try the related loot
Give OpenClaw Agents Pre-Verified Web Actions with Actionbook